Foreword
A traffic spike during a flash sale, a live stream peak, or a breaking news event can push an origin server from idle to overloaded in seconds. Single-tier CDNs often fail in this scenario because every edge node that misses a cache forwards the request straight to the origin. When thousands of edge nodes miss the same hot object at the same moment, the origin receives thousands of identical requests, and the result is a cascading failure. This article describes in detail how multi-tier CDN architecture with L1, L2, and L3 layers absorbs traffic spikes, and which performance metrics reveal whether the architecture is actually working.
Why single-tier CDN fails under spike load
A single-tier CDN has one caching layer between users and the origin. The request path is direct: user → edge node → origin. This works fine for normal traffic, but the math breaks down during a spike.
Edge nodes fail as a group: When thousands of edge nodes are hit simultaneously, each one independently tries to fetch the missing content. There is no coordination between them, so the origin sees a surge of duplicate requests.
Origin requests overlap heavily: If 10,000 users request the same object and the edge node does not have it cached, a single-tier CDN sends 10,000 requests to the origin. The origin's bandwidth and database connections are exhausted.
Bandwidth spike hits the origin directly: The origin has no buffer between itself and the edge layer. A sudden surge in cache misses translates into a sudden surge in origin bandwidth consumption.
Cascading failure: Once the origin becomes unresponsive, even users whose requests were not part of the spike are affected. The entire service goes down, not just the hot content.
The core problem is that a single-tier CDN has no mechanism to merge duplicate requests or buffer the origin from the edge layer. It amplifies origin pressure instead of absorbing it.
How multi-tier CDN architecture works
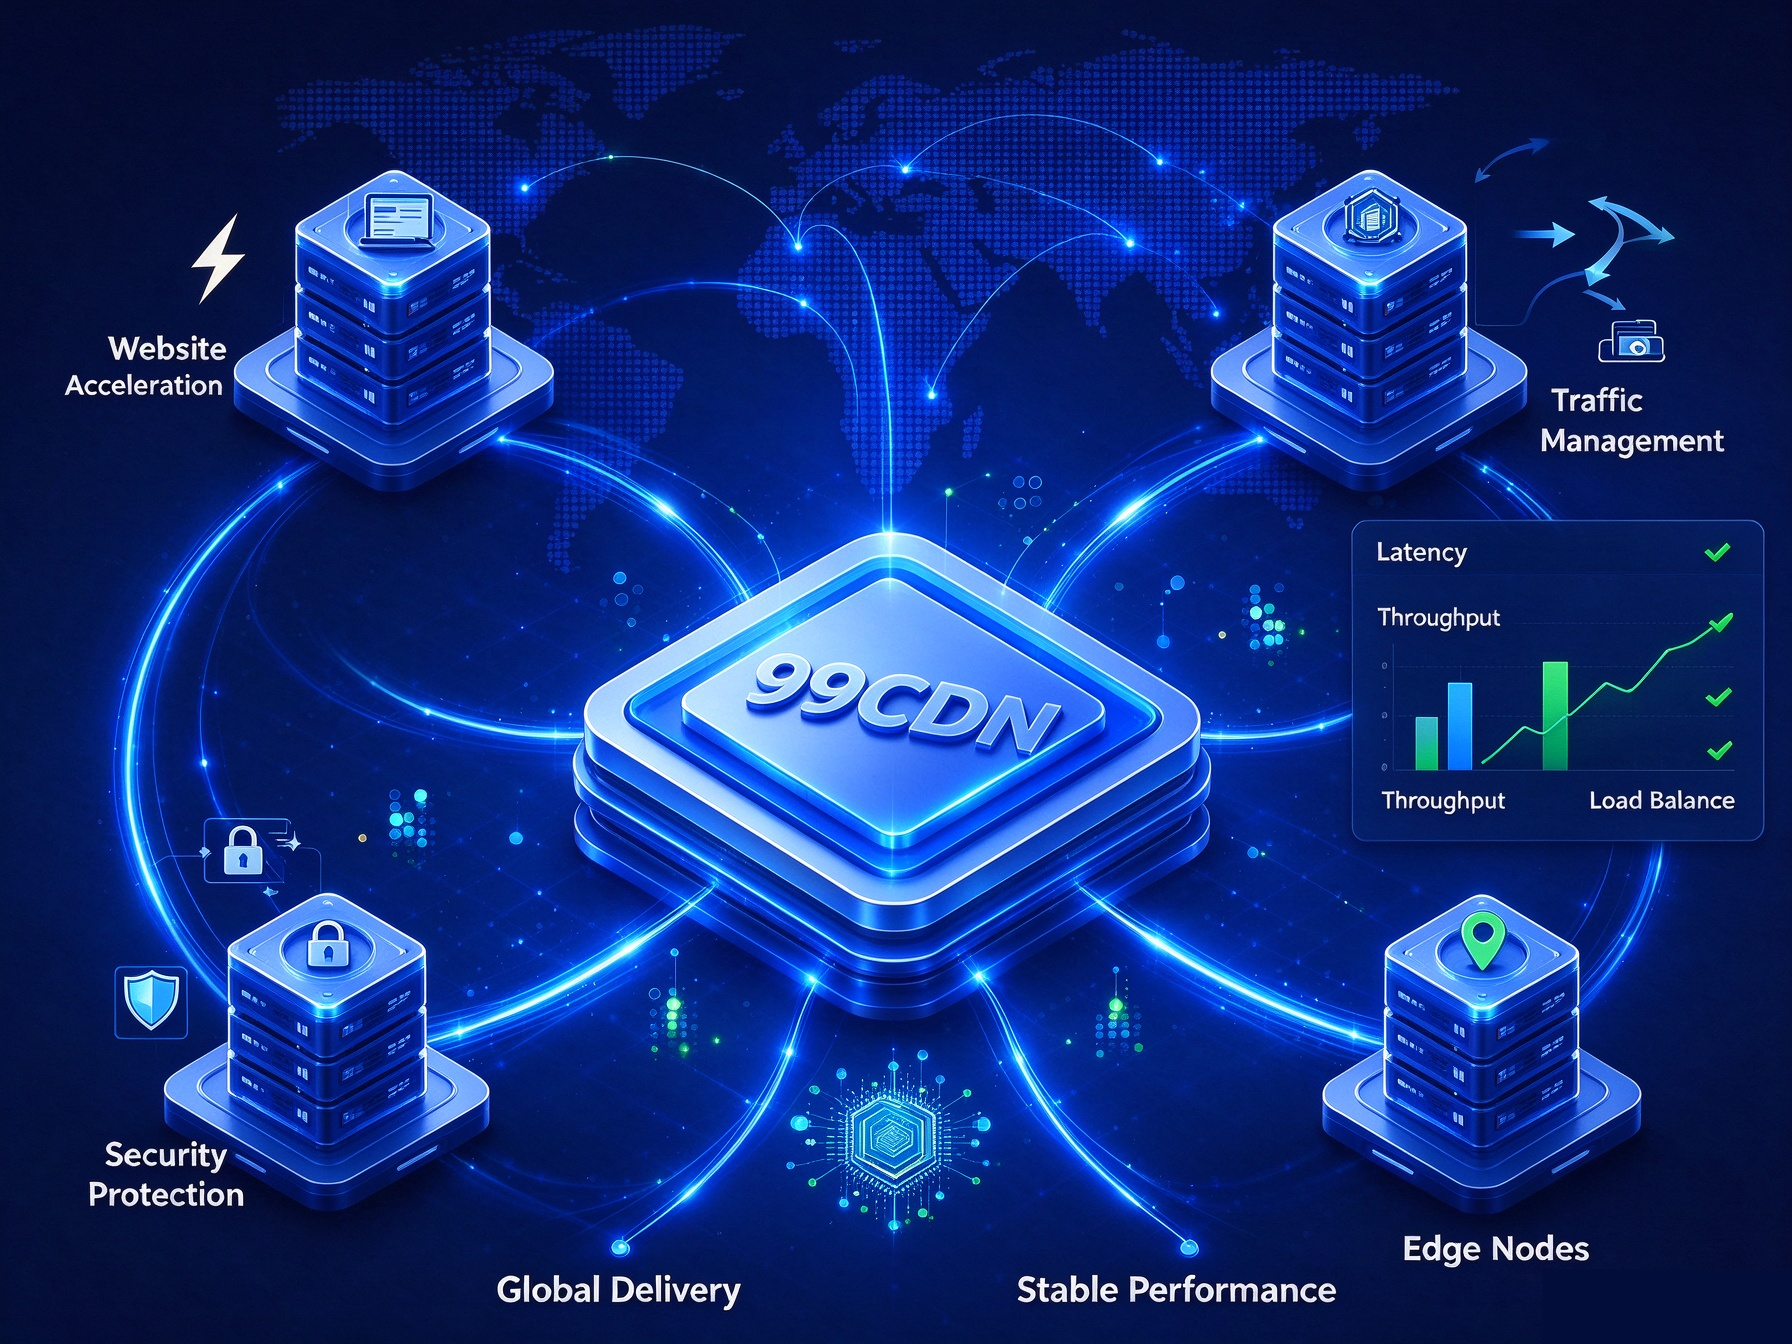
A multi-tier CDN architecture inserts intermediate cache layers between the edge and the origin. The standard layout is L1 (edge), L2 (regional), and L3 (central).
L1 edge layer: The first line of defense. Edge nodes sit closest to users and handle the majority of cache hits. In a well-tuned deployment, L1 absorbs 80% or more of repeated requests without contacting any upper layer.
L2 regional layer: When multiple L1 nodes miss the same object, they do not all go to the origin. They forward requests to a shared L2 node, which aggregates them.
L3 central layer: The final cache layer before the origin. L3 handles requests that L2 cannot satisfy and performs the last round of request merging before the origin is contacted.
Origin: Only receives requests that no cache layer could satisfy, and only after duplicates have been merged at L2 or L3.
The request path becomes: user → L1 → L2 → L3 → origin. Each layer reduces the number of requests that reach the next layer.
Request collapsing: the core mechanism
Request collapsing is what makes multi-tier architecture effective during a spike. When multiple L1 nodes request the same object at the same time, the L2 node collapses those requests into a single origin fetch.
Without collapsing: 100 L1 nodes miss the same object, send 100 requests to L2, and L2 forwards 100 requests to the origin.
With collapsing: 100 L1 nodes miss the same object, send 100 requests to L2, and L2 merges them into 1 origin request. The remaining 99 requests wait in a queue and are served from the fetched object once it arrives.
Result: The origin sees 1 request instead of 100. The origin offload ratio improves dramatically, and the origin's bandwidth consumption stays flat even as edge request volume grows.
This mechanism is why multi-tier CDNs can handle traffic spikes that would overwhelm a single-tier setup. The origin is protected by the L2 and L3 layers, which act as request aggregators rather than simple forwarders.
Measuring the impact: origin offload ratio and P99 latency
Two metrics reveal whether a multi-tier CDN is actually absorbing a traffic spike.
Origin offload ratio: The percentage of requests served without reaching the origin. In a single-tier CDN under spike load, this ratio can drop below 50% because cache misses go straight to the origin. In a multi-tier CDN with request collapsing, the ratio stays above 90% even during spikes, because L2 and L3 absorb the misses.
P99 latency: The latency experienced by the slowest 1% of requests. In a single-tier CDN, P99 latency spikes sharply when the origin is overwhelmed, because requests queue at the origin. In a multi-tier CDN, P99 latency stays stable because the origin is shielded and edge nodes serve cached content directly.
A practical benchmark compares these two metrics under three conditions: normal traffic, moderate spike (5x normal), and severe spike (50x normal). A well-architected multi-tier CDN shows minimal change in both metrics across all three conditions.
What this means for infrastructure selection
For teams running high-concurrency workloads, the choice of CDN architecture matters more than the number of edge nodes.
Single-tier CDN is sufficient for low-traffic sites where cache misses are rare and the origin has headroom.
Multi-tier CDN becomes necessary when the origin cannot absorb duplicate requests during spikes, or when P99 latency requirements are strict.
Custom CDN deployments allow tuning the L1/L2/L3 ratio, cache expiration policies, and request collapsing rules to match specific traffic patterns.
Bare metal origin servers pair well with multi-tier CDNs because they provide dedicated bandwidth and CPU, so the origin can handle the reduced request volume without competing with other tenants.
Summary
Multi-tier CDN architecture absorbs traffic spikes by inserting L2 and L3 cache layers between the edge and the origin. These layers perform request collapsing, merging duplicate requests into a single origin fetch. The result is a high origin offload ratio and stable P99 latency even under severe spike conditions.
Single-tier CDNs fail during spikes because they amplify origin pressure. Multi-tier CDNs succeed because they absorb it. For teams with strict latency and availability requirements, the architecture choice is the difference between a service that degrades gracefully and one that fails completely.
Thank you very much for reading to the end!